QuestionQ63

Performance, Cost, and Resource Optimization

A table for IoT devices that measure water usage is created. The table rapidly grows to contain more than 2 billion rows.
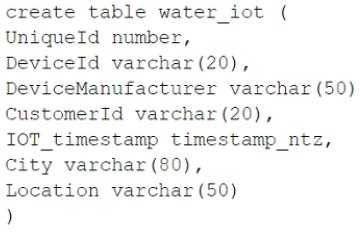
Question Image

The general query patterns for the table are:

  1. DeviceId, IOT_timestamp, and CustomerId are frequently used in SELECT filter predicates.
  2. The City and DeviceManufacturer columns are often retrieved.
  3. UniqueId is often counted.

Which field(s) should be used for the clustering key?

Explanation

Clustering keys are chosen primarily from columns frequently used in selective filter predicates because they allow micro-partition pruning. DeviceId and CustomerId match that workload, whereas retrieved-only columns do not aid pruning and a unique identifier is generally too high-cardinality to be cost-effective as a clustering key. A highly granular timestamp may also be unsuitable directly without reducing its cardinality through an expression.

Learn more

Community Discussion

No comments yet. Be the first to start the discussion!