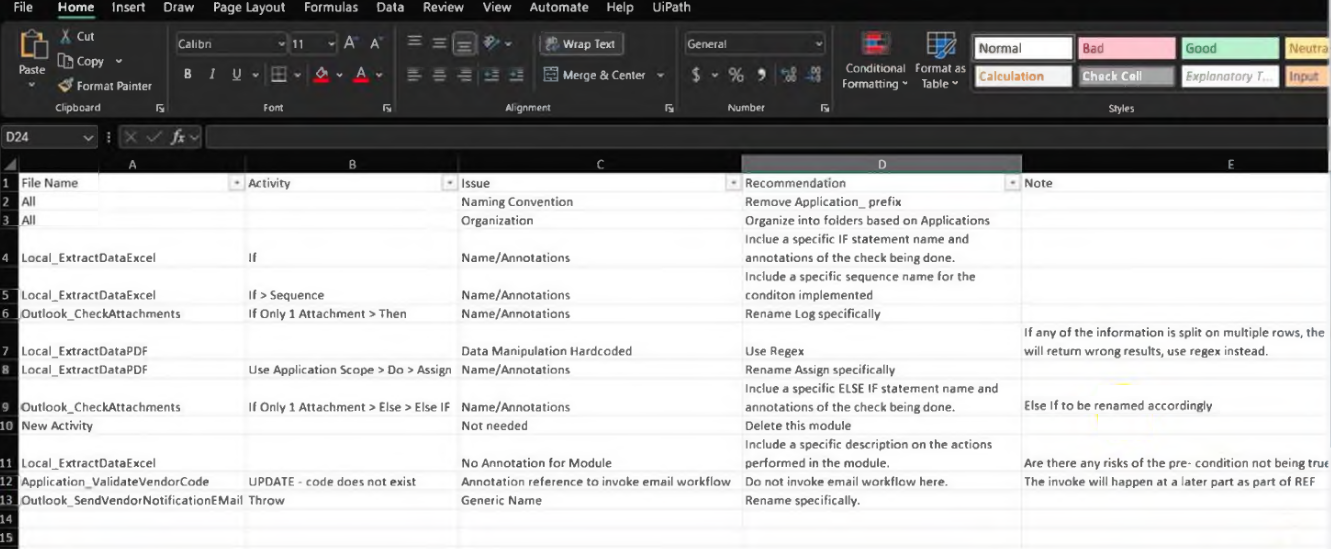
A code-review severity rating should scale with the functional risk the underlying issue poses — for instance, an issue that causes data to be silently split across rows and produce wrong results (recommended fix: use Regex) or an issue involving hardcoded application logic in an Excel data-extraction workflow represents a materially higher risk than a naming-convention or annotation-wording issue, yet several rows in the review output assign these dissimilar issues comparable severity levels. Systematically comparing each row's assigned severity against the actual risk profile described in its Issue and Note columns turns up five such mismatches, where the recorded severity does not reflect whether the underlying defect is a cosmetic naming/documentation gap or a substantive functional or data-integrity risk.
Community Discussion