Snowflake Cortex Guard is a built-in safeguard for the COMPLETE function (and its Python equivalent, snowflake.cortex.complete) that filters potentially unsafe or harmful language from an LLM's response, regardless of the prompt content. It is built on Meta's Llama Guard 3 model and evaluates the generated response before it is returned; if unsafe content (e.g., related to violence, hate, self-harm, sexual content, etc.) is detected, the response is replaced with a filtered message. Cortex Guard is enabled by setting the 'guardrails' parameter to True inside the options object passed to the function — in Python this is done via CompleteOptions(guardrails=True). Other CompleteOptions parameters, such as temperature, top_p, max_tokens, stream, or response_format, control aspects like randomness, output length, streaming behavior, or structured JSON formatting, and do not perform content-safety filtering.
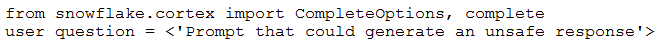
Community Discussion