QuestionQ71
VerifiedPrepare dataHOTSPOT
You have a Fabric workspace that uses the default Spark starter pool and runtime version 1.2.
You plan to read a CSV file named Sales_raw.csv in a lakehouse, select columns, and save the data as a Delta table to the managed area of the lakehouse. Sales_raw.csv contains 12 columns.
You have the following code.
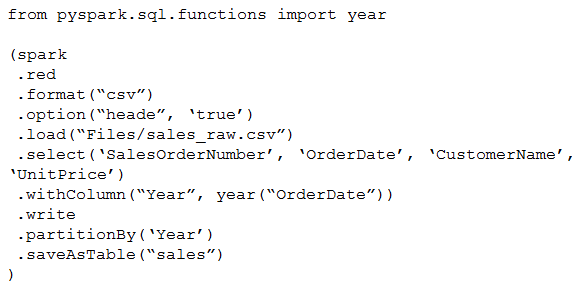
For each of the following statements, select Yes if the statement is true. Otherwise, select No.
Yes or No
| Statements | Yes | No |
|---|---|---|
| The Spark engine will read only the 'SalesOrderNumber', 'OrderDate','CustomerName', 'UnitPrice' columns from Sales_raw.csv. | ||
| The Year column replaces the OrderDate column in the table. | ||
| Adding inferSchema='true' to the options will increase the execution time of the query. |
Community Discussion