QuestionQ73
VerifiedServing and scaling modelsYou trained a TensorFlow DNN regressor to predict housing prices from predictive features. Your default precision is tf.float64, and you use a standard TensorFlow estimator:
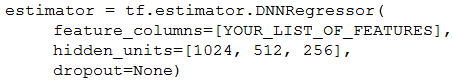
The model performs well, but immediately before production deployment you find that serving latency is 10 ms at the 90th percentile and that you currently serve on CPUs. Production requires model latency of 8 ms at the 90th percentile. You are willing to accept a small reduction in performance to meet the latency requirement.
Therefore, you plan to improve latency while evaluating the amount by which the model's predictions decrease. What should you try first to quickly reduce serving latency?
Community Discussion