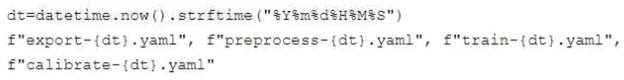
You developed a Vertex AI pipeline that trains a classification model on data stored in a large BigQuery table. The pipeline has four steps, each created by a Python function that uses the KubeFlow v2 API. The components have the following names:
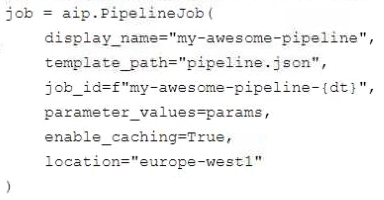
You launch the Vertex AI pipeline as follows:
You perform many model iterations by adjusting the code and parameters of the training step. You observe high development costs, particularly for the data-export and preprocessing steps. You need to reduce model-development costs. What should you do?
Community Discussion
No comments yet. Be the first to start the discussion!
Community Discussion